New: Mira, your AI research agent
New: Mira, your AI research agent
Describe your study to Mira, our AI research agent. Mira searches every dataset in the Hub and tells you in under 15 minutes whether we have the data you need.
Describe your study to Mira, our AI research agent. Mira searches every dataset in the Hub and tells you in under 15 minutes whether we have the data you need.
Ask Mira
Describe your cohort in plain language. Mira shows you which datasets match and how many patients fit.
Ask Mira
Describe your cohort in plain language. Mira shows you which datasets match and how many patients fit.
Explore Right Away
Start on a privacy-safe version* of each dataset. No IRB or DUA needed to explore.
Explore Right Away
Start on a privacy-safe version* of each dataset. No IRB or DUA needed to explore.
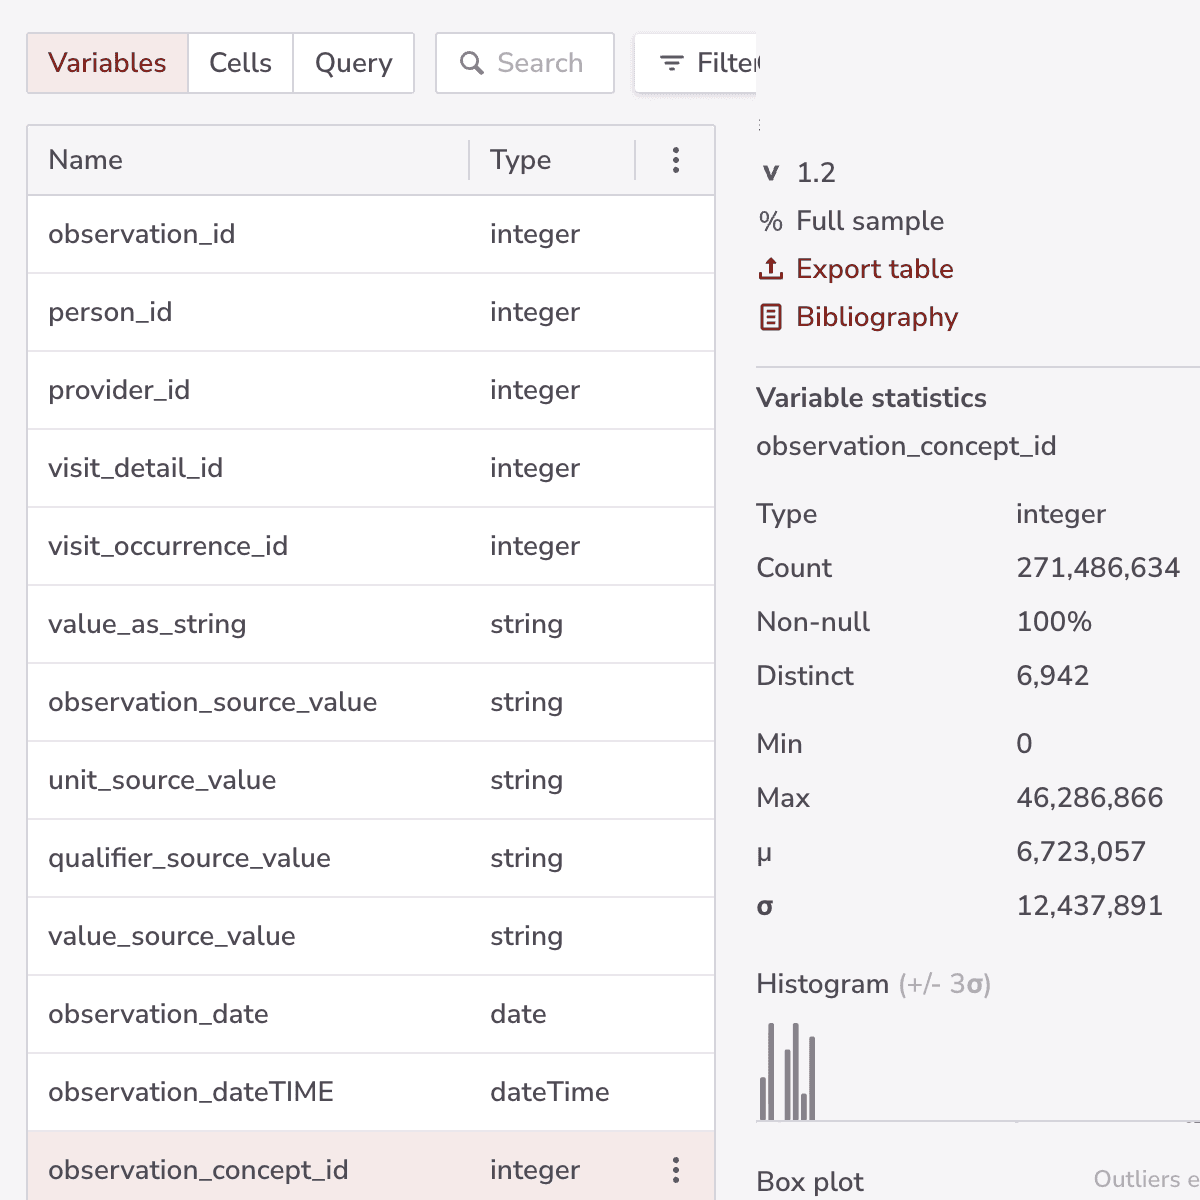
Research-Ready Workspace
When you're ready to go deeper, Mira takes you into a cloud workspace with Python, R and SQL.
Research-Ready Workspace
When you're ready to go deeper, Mira takes you into a cloud workspace with Python, R and SQL.
Validate on Real Data
Run your finished analysis on real patient-level data in a controlled, privacy-preserving workflow.
Validate on Real Data
Run your finished analysis on real patient-level data in a controlled, privacy-preserving workflow.
*Privacy-safe versions are statistical replicas built from the real dataset. They contain no real patient records.
01
Ask Mira
Tell Mira what you're studying. In under 15 minutes it finds the datasets that fit and sizes your cohort.
01
Ask Mira
Tell Mira what you're studying. In under 15 minutes it finds the datasets that fit and sizes your cohort.
02
Explore & Build
Open the dataset in your Hub workspace and build your analysis on a privacy-safe version,* with no IRBs, DUAs or long approvals.
02
Explore & Build
Open the dataset in your Hub workspace and build your analysis on a privacy-safe version,* with no IRBs, DUAs or long approvals.
03
Validate on Real Data
Run your finalized code on real patient-level datasets in a controlled, privacy-preserving workflow.
03
Validate on Real Data
Run your finalized code on real patient-level datasets in a controlled, privacy-preserving workflow.
Answers to common questions about Mira, our datasets, and how access works.
Not sure we have your data? Mira can tell you.
How quickly can I start working with the data?
You can begin exploring anonymized simulated patient data immediately after signing up — no IRBs, DUAs, or legal reviews required. Everything is ready to go in a secure, pre-configured environment designed for fast onboarding and rapid iteration.
What kind of research can I do with simulated data?
Simulated data is ideal for exploratory analysis, hypothesis testing, model development, and validation workflows. It mirrors real-world patient distributions and care patterns, letting you build and refine methods before moving to actual patient-level datasets — all without compliance delays.
How does validation on real data work?
Once your analysis or model is ready, you can run it on our real-world de-identified patient datasets. We provide a controlled environment to execute your code securely, ensuring your findings are robust, reproducible, and grounded in actual patient data — without compromising privacy.
What programming languages and tools can I use?
You can work in Python, R, SQL, or SAS — all accessible through a Jupyter-based environment preconfigured for healthcare data science. Our platform runs on a scalable cloud backend with both CPU and GPU options, so you can go from analysis to model training without changing environments or waiting on infrastructure.
Mira, our AI research agent, searches the Hub's datasets and gives you an answer in under 15 minutes. When you're ready, keep working in a secure cloud workspace and validate on real patient data.